AI Infrastructure
AI Infrastructure, Designed as One System
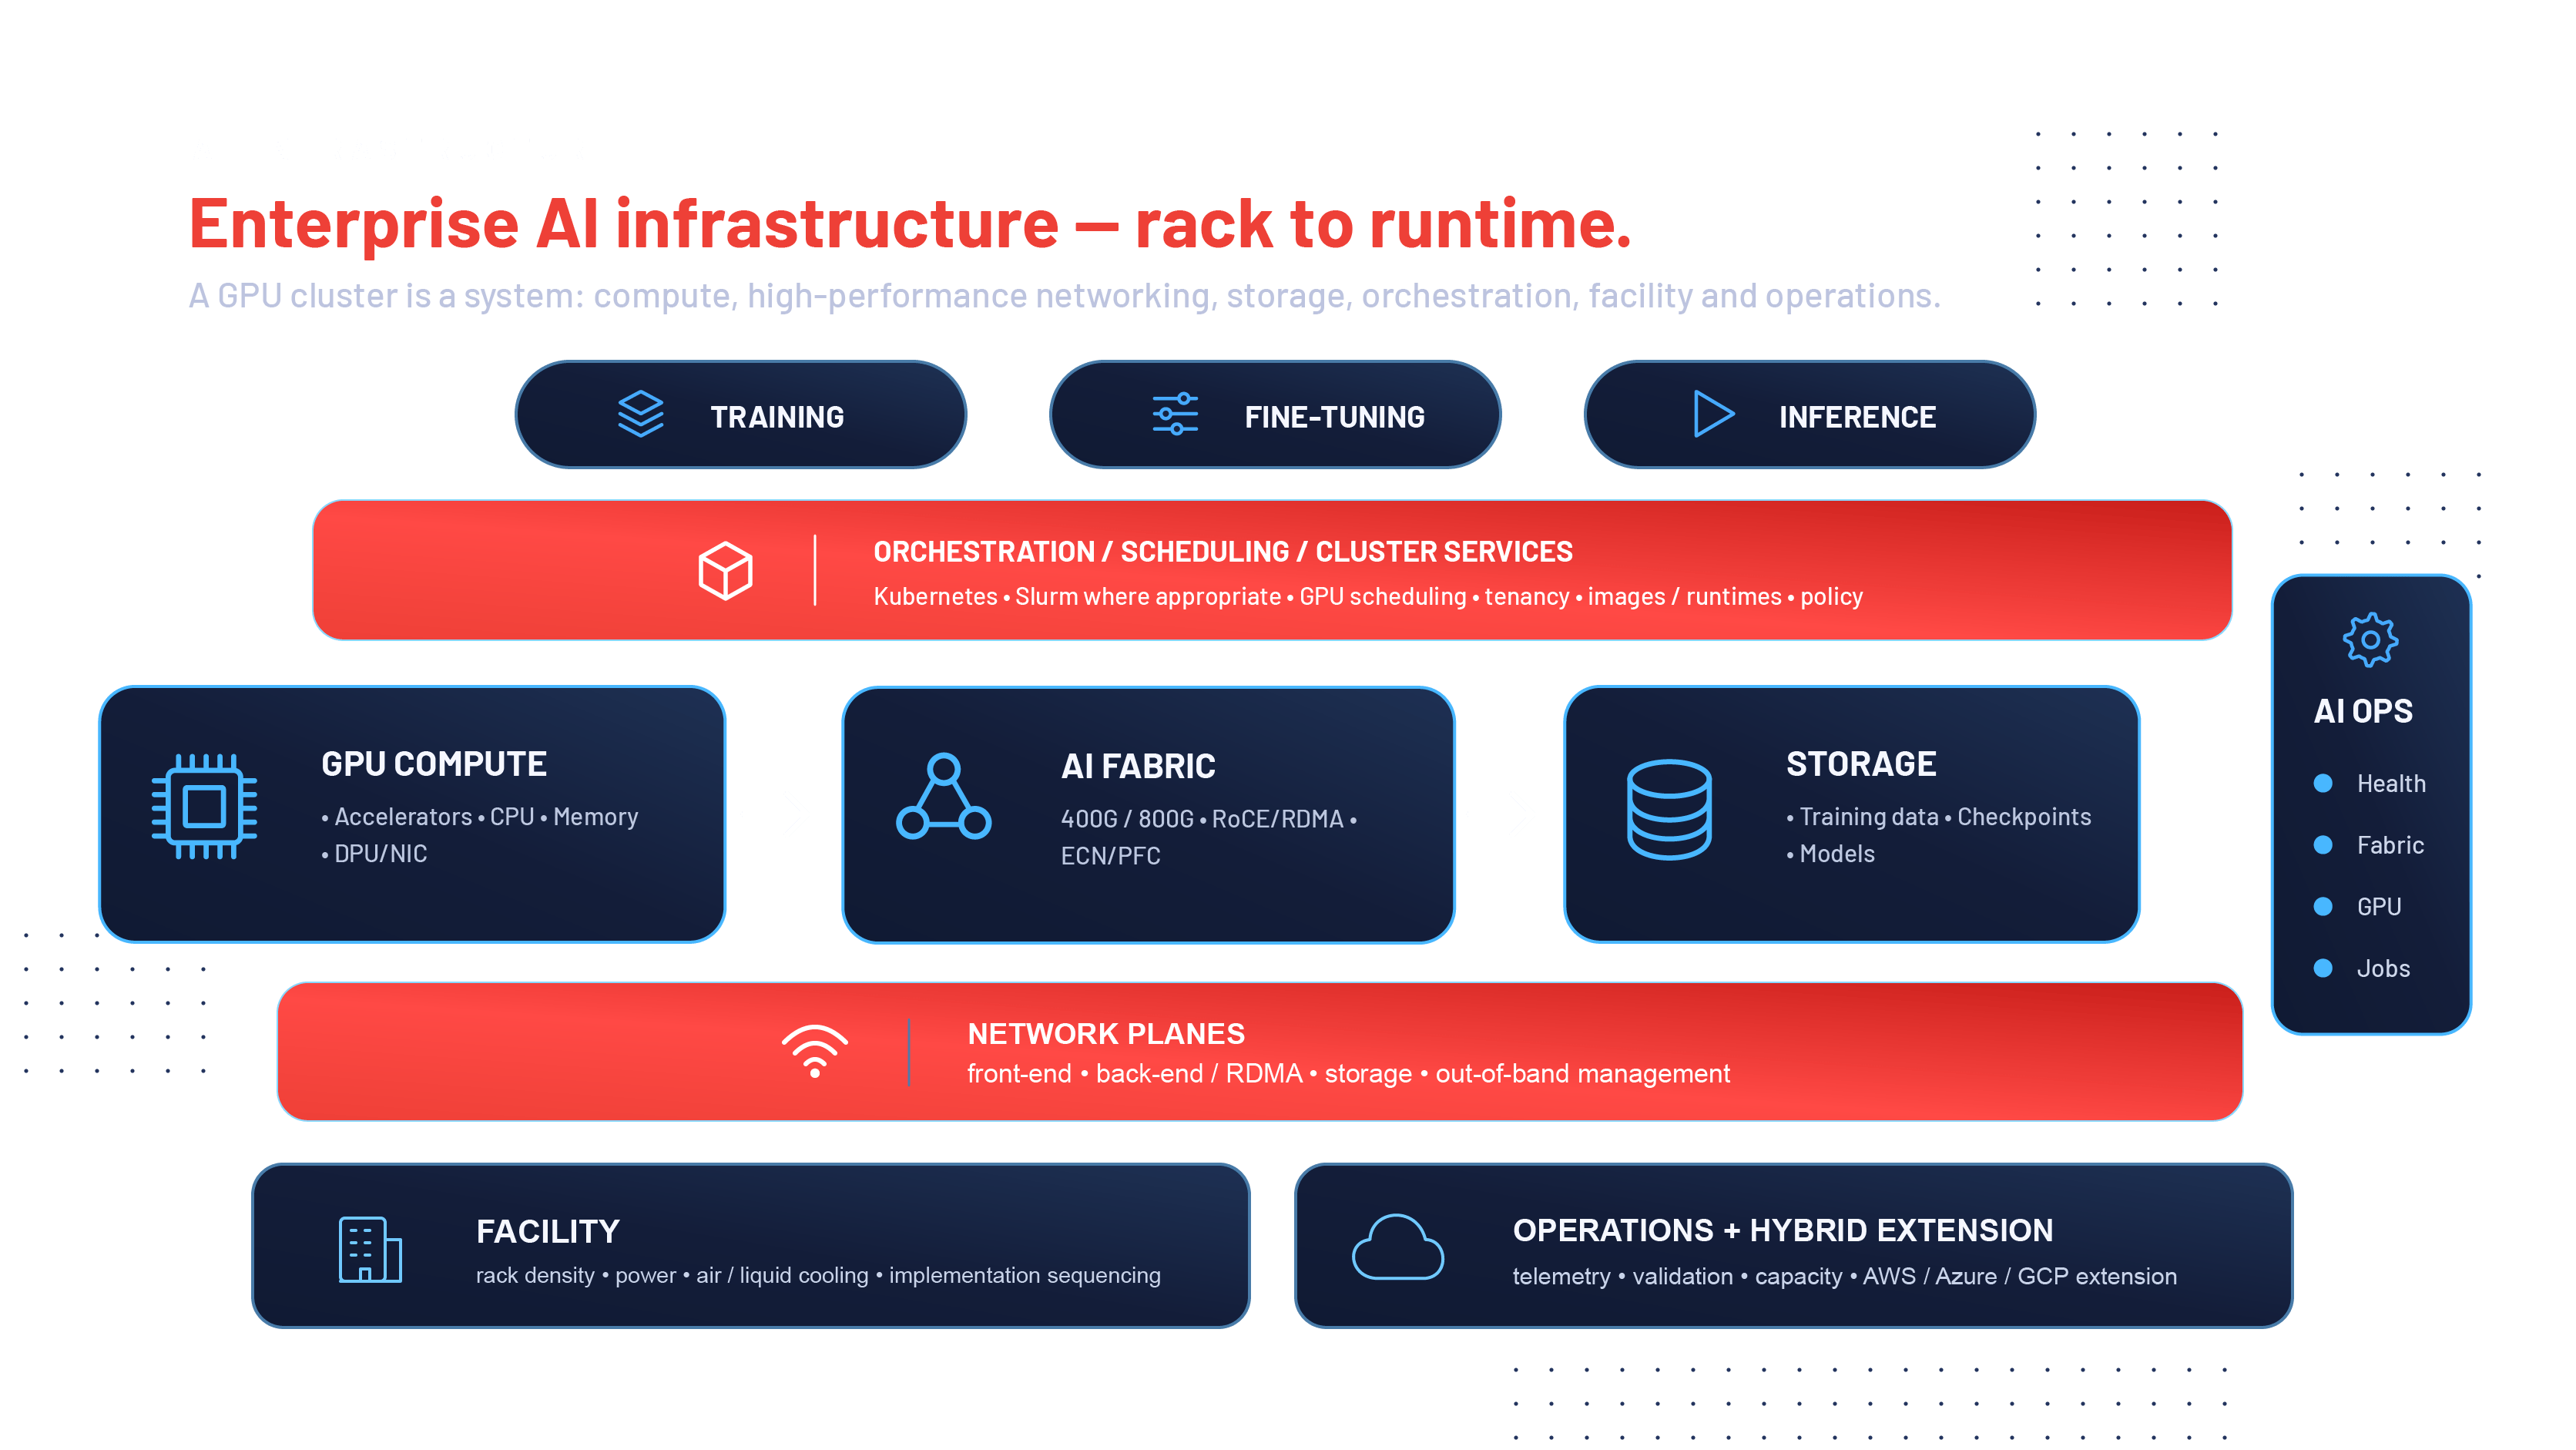
AI infrastructure requires the compute, network, storage, power and cooling to be designed as one system. Driven designs and deploys the networking, compute, storage, orchestration, power and cooling required to run AI training and inference on-premises, at the edge and in public cloud. GPU utilization depends on the network, storage, scheduling, power and cooling around the compute.
400G/800G
HIGH-PERFORMANCE AI FABRICS
2
PRIMARY WORKLOAD CLASSES: TRAINING + INFERENCE
3
DEPLOYMENT MODELS: CORE / EDGE / CLOUD
1
SYSTEM: COMPUTE + NETWORK + STORAGE + POWER + COOLING
Workload evaluation
Size the platform from the workload requirements.
Training a model, fine-tuning an existing model, and serving inference have different performance, latency, memory, storage, and network requirements. Before selecting a platform, we work backward from the workload: model size, dataset, concurrency, throughput, latency, location, data residency, growth, tenancy, and operational expectations.
GPU Compute & Node Architecture
AI teams need GPU systems sized around the actual workload so expensive accelerators are not limited by the wrong CPU, memory, network, or node design. GPU server selection, CPU/GPU balance, memory, NIC/DPU design, node roles, rack layout, management interfaces, and scale planning.
Rack-to-runtime validation
Enterprise AI infrastructure / AI factory
Before handoff, validate the full path: node health, optics and cabling, fabric loss/latency, RDMA behavior, storage throughput, GPU telemetry, scheduling, failure scenarios, software/firmware baselines and representative workload performance. A cluster is not finished because every device powers on.
Strategic Technology Partners
View Our Partners
Ready to start